Writing from the Reflexio team

Product updates, engineering notes, and ideas on building agents that learn.

7 min read

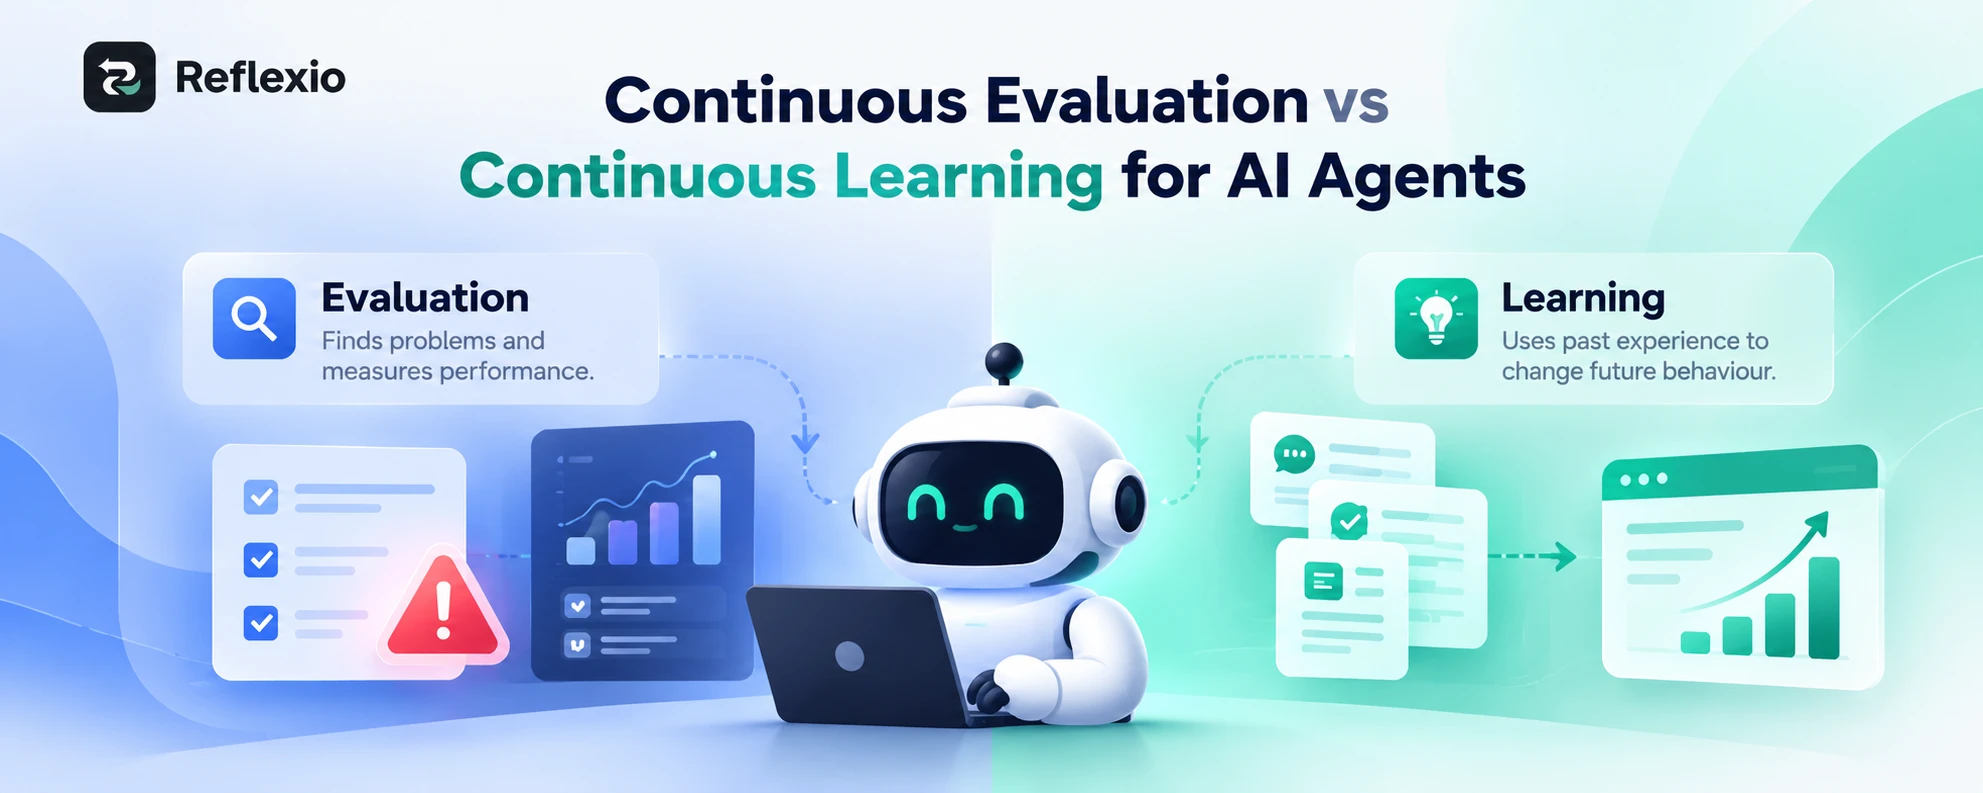
Continuous Evaluation vs Continuous Learning for AI Agents

The article explains the difference between continuous evaluation, which tests agent performance, and continuous learning, which turns past experience into reusable lessons that change future behavior, and describes how the platform Reflexio combines both approaches to help AI agents avoid repeating mistakes.

RTReflexio Team
11 min read

How to Measure AI Agent Behavior Improvement

A step-by-step guide on measuring AI agent behavior improvement, covering how to establish a baseline, select task-specific metrics such as success rate and retries, compare results before and after changes, and verify whether learning leads to lasting gains without regressions.

RTReflexio Team
11 min read

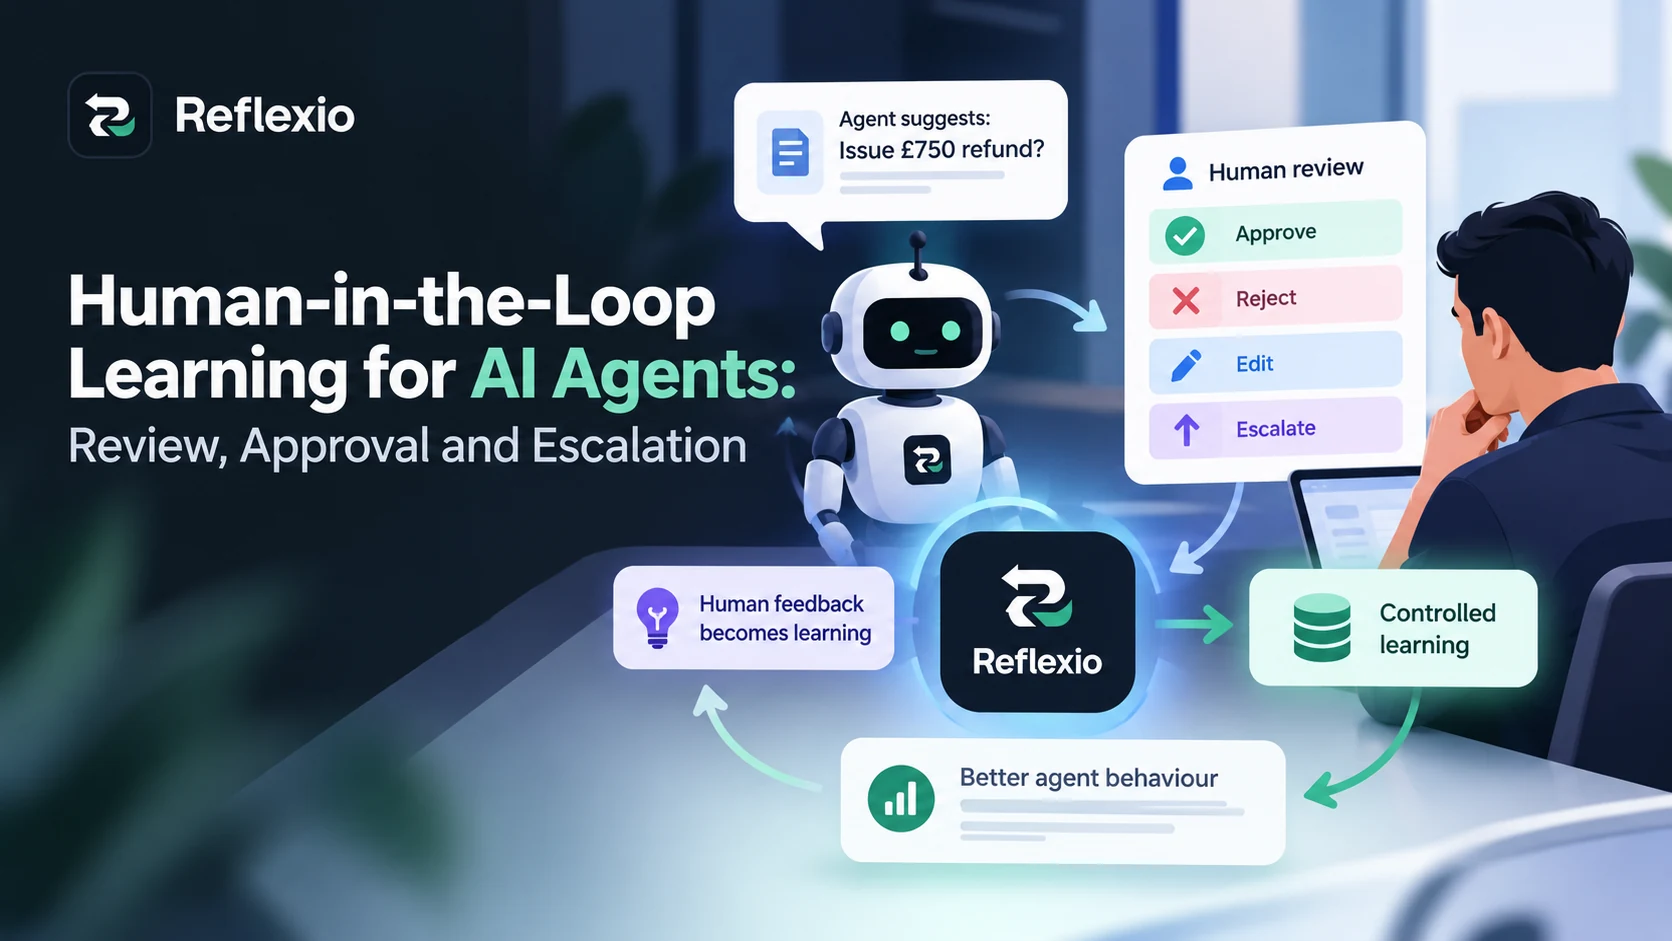
Human-in-the-Loop Learning for AI Agents: Review, Approval and Escalation

Learn when AI agents should act, request approval or escalate, and how human corrections can become reusable, controlled behavioural learning.

RTReflexio Team
10 min read

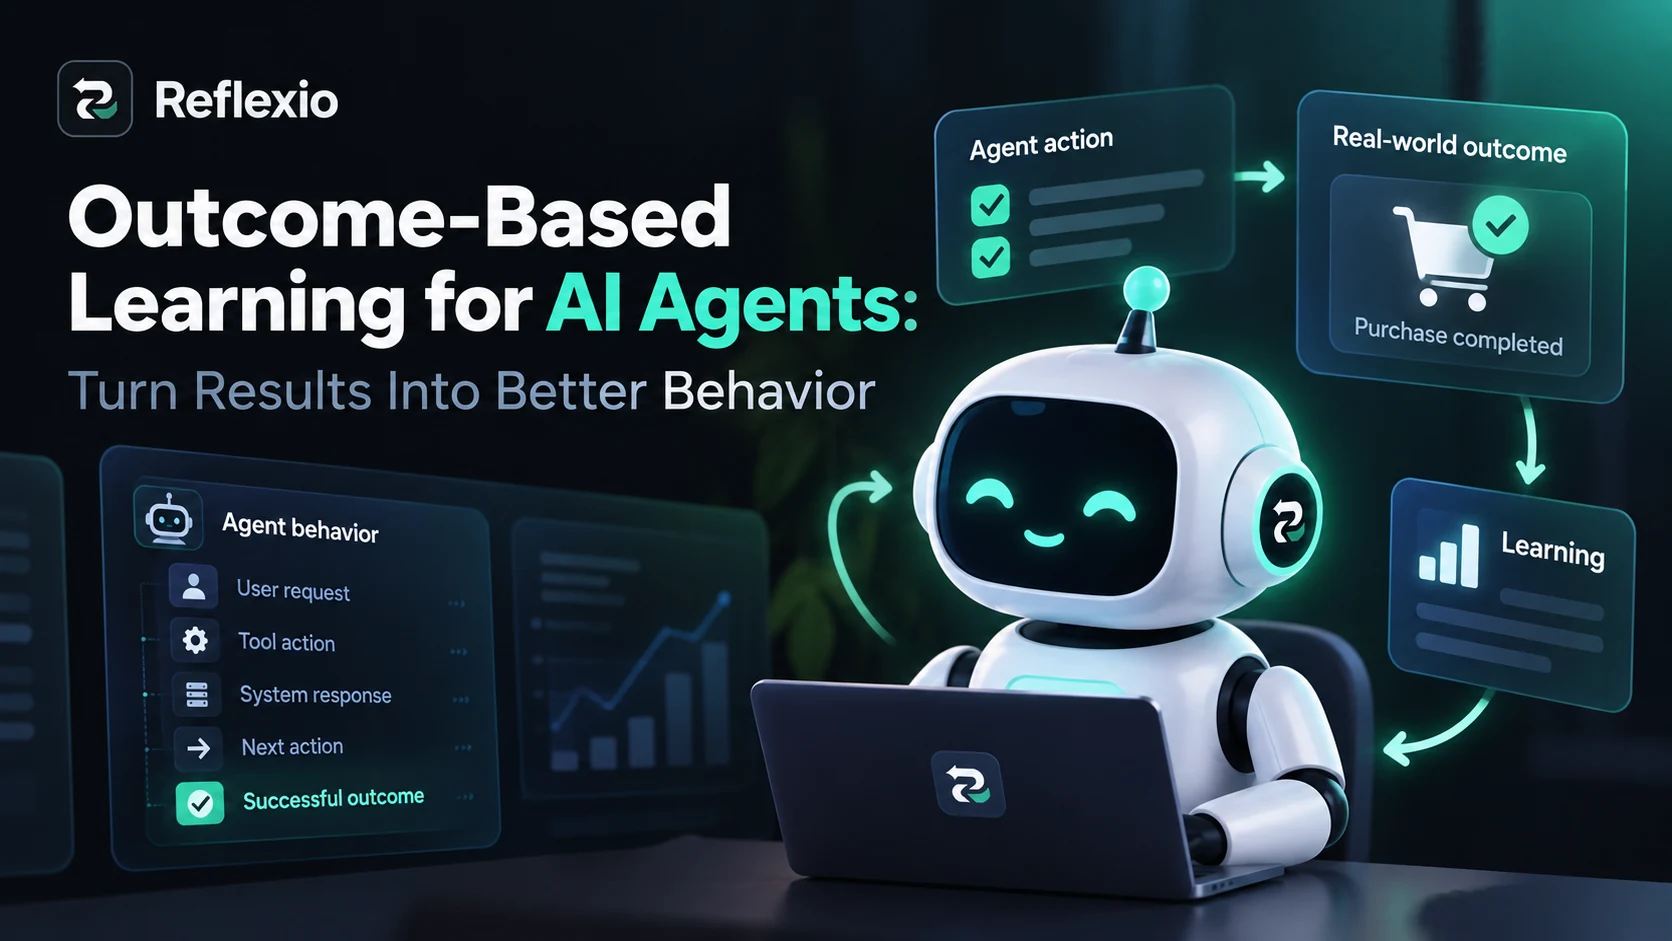
Outcome Based Learning for AI Agents: Turn Results Into Better Behavior

Explore how production outcomes, successful actions and failed paths can provide evidence for improving AI agent behaviour.

RTReflexio Team
13 min read

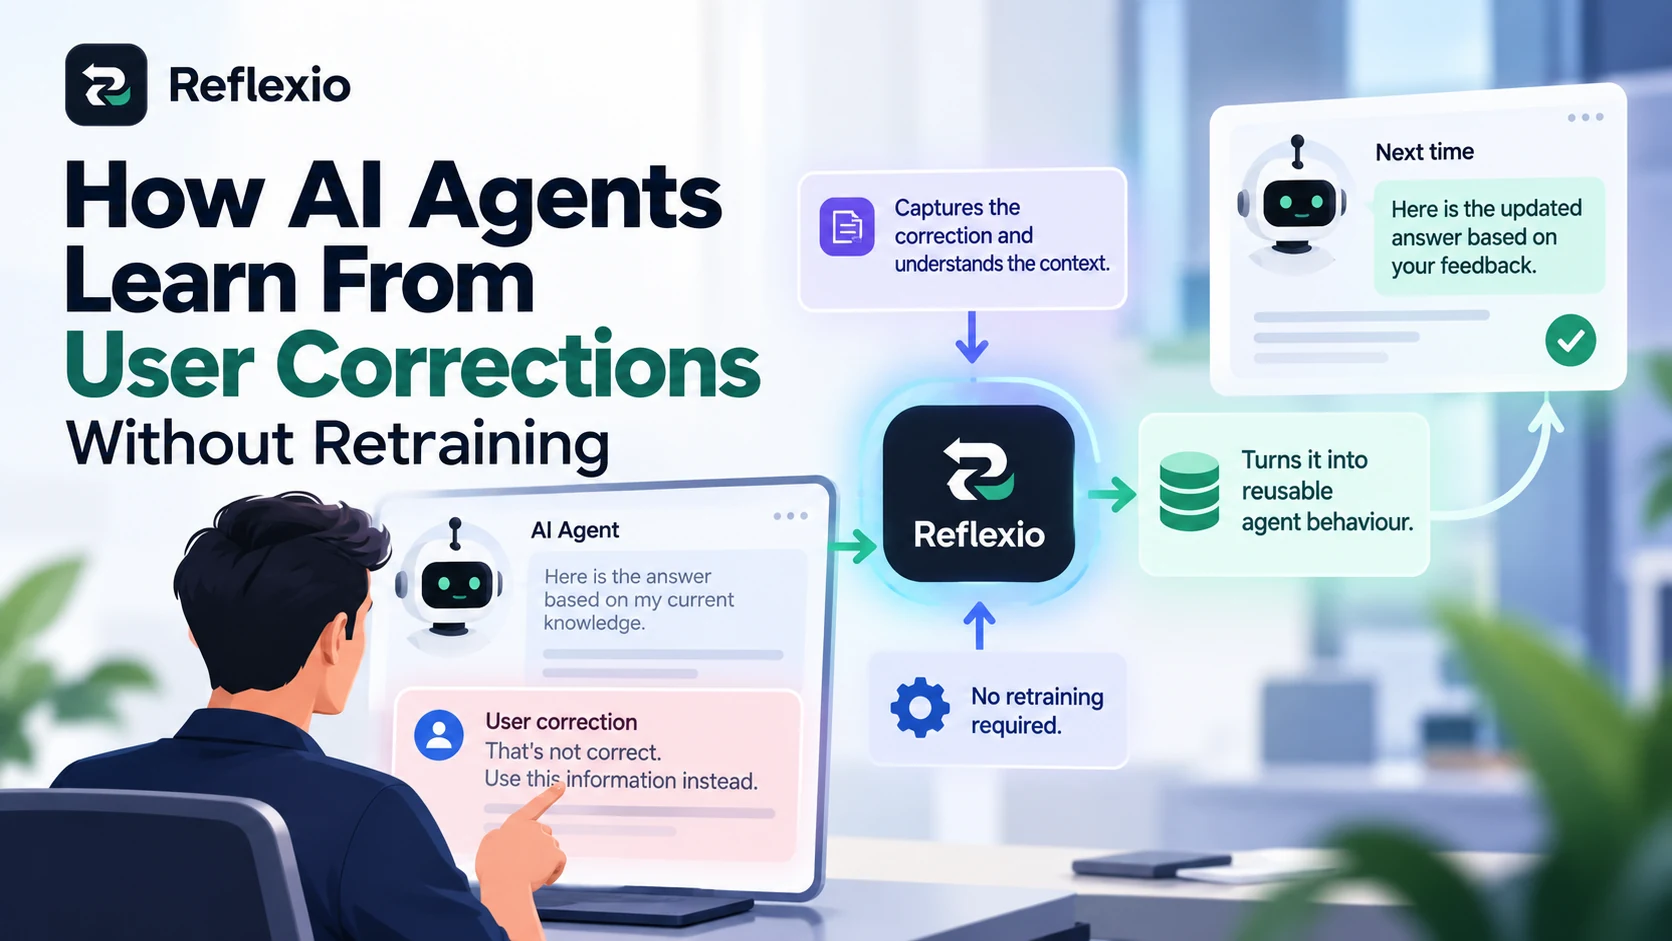
How AI Agents Learn From User Corrections Without Retraining

Learn how AI agents can turn user corrections into evaluated, reusable behavioural guidance without retraining the underlying model.

RTReflexio Team
8 min read

Everyone Is Building Self-Improving Agents. Almost Nobody Means the Same Thing.

A nightly fine-tune and a one-line note appended to a markdown file are both sold as agents that learn from experience. They are the same loop with different parts swapped out. This is a map of the field: what changes, what decides, and when — and why the second question is the one that separates methods that compound from methods that only look like they do.

RTReflexio Team
9 min read

Your Agent Dreams. It Still Can't Tell You If It Got Better.

Dreaming makes an agent's memory better. Only measurement makes the agent better. Anthropic's Dreams, ChatGPT, Codex, Gemini CLI and OpenClaw all rewrite agent memory offline — and every gate they document checks whether the rewritten memory is tidy, not whether the agent improved.

RTReflexio Team
7 min read

How Creao Turned Agent Exploration Into Repeatable Execution

Creao used Reflexio to turn successful agent behavior into reusable guidance—cutting median model calls by 75%, reducing task failures by 36%, and showing positive impact from retrieved learnings in 47% of evaluated cases.

RTReflexio Team
8 min read

Your Agent Remembers Everything and Learns Nothing

AI memory and agent self-improvement sit in the same slot, use the same storage, and are sold against the same failure — which is why they get confused. The difference is what has to happen before the system writes anything down. One writes when something is said. The other writes when something is judged.

RTReflexio Team
8 min read

From Loop Engineering to Self-Improvement: The Loop Over Loops

Loop engineering is how we get agents to iterate toward a goal on their own. Self-improvement is the next stage — a loop wrapped around those loops, so each pass makes the next one better. This is a field note on how the two ideas connect.

RTReflexio Team
8 min read

Learn, Generalize, Reflect and Optimize (LGRO): A Practical Guide for Self-Improving AI Agents

Memory remembers what happened. Learning changes what the agent does next time. LGRO — Learn, Generalize, Reflect, Optimize — is a practical framework for non-parametric, self-improving AI agents.

RTReflexio Team